Stable Diffusion 3.5 Large
Detailed generations with negative prompts and image-to-image for fine control.
- Detailed art
- Image-to-image
- Fine control
Made with Stable Diffusion 3.5 Large
Real output from our prompts, unedited.
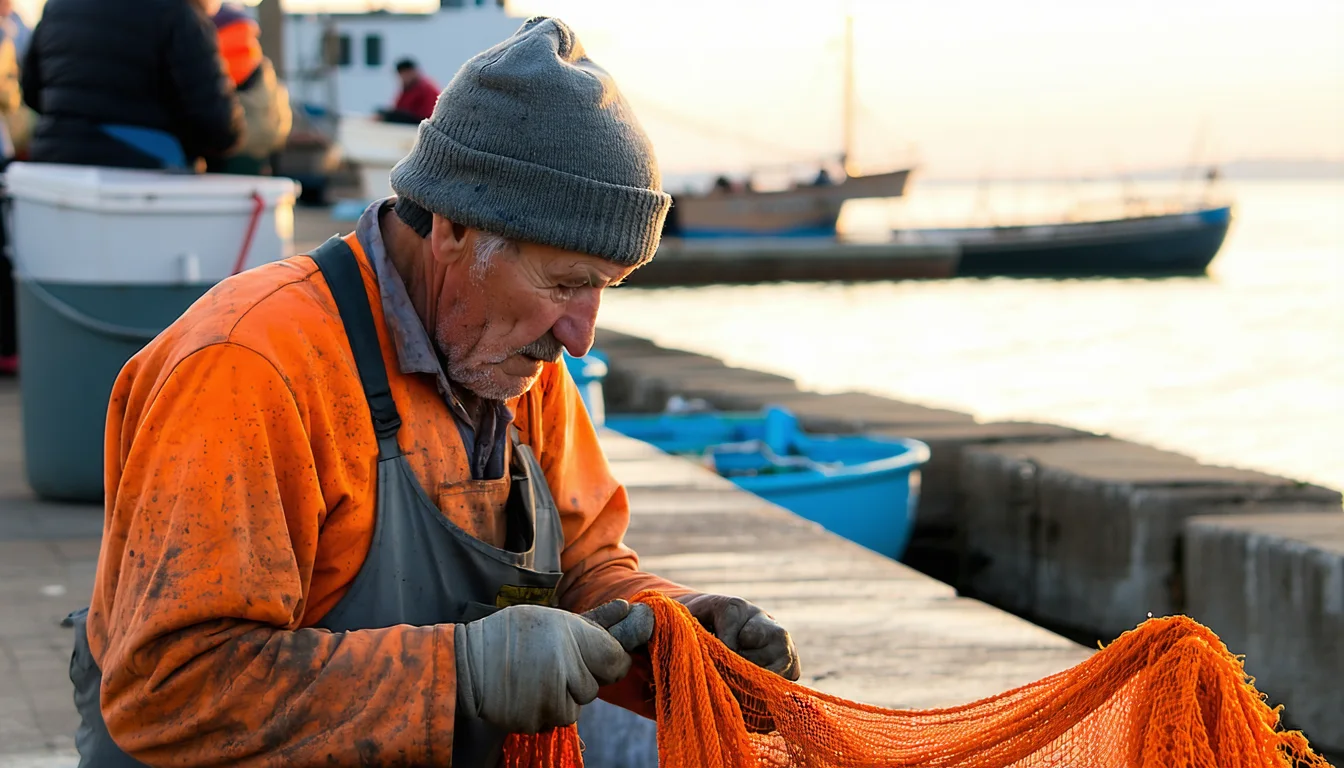
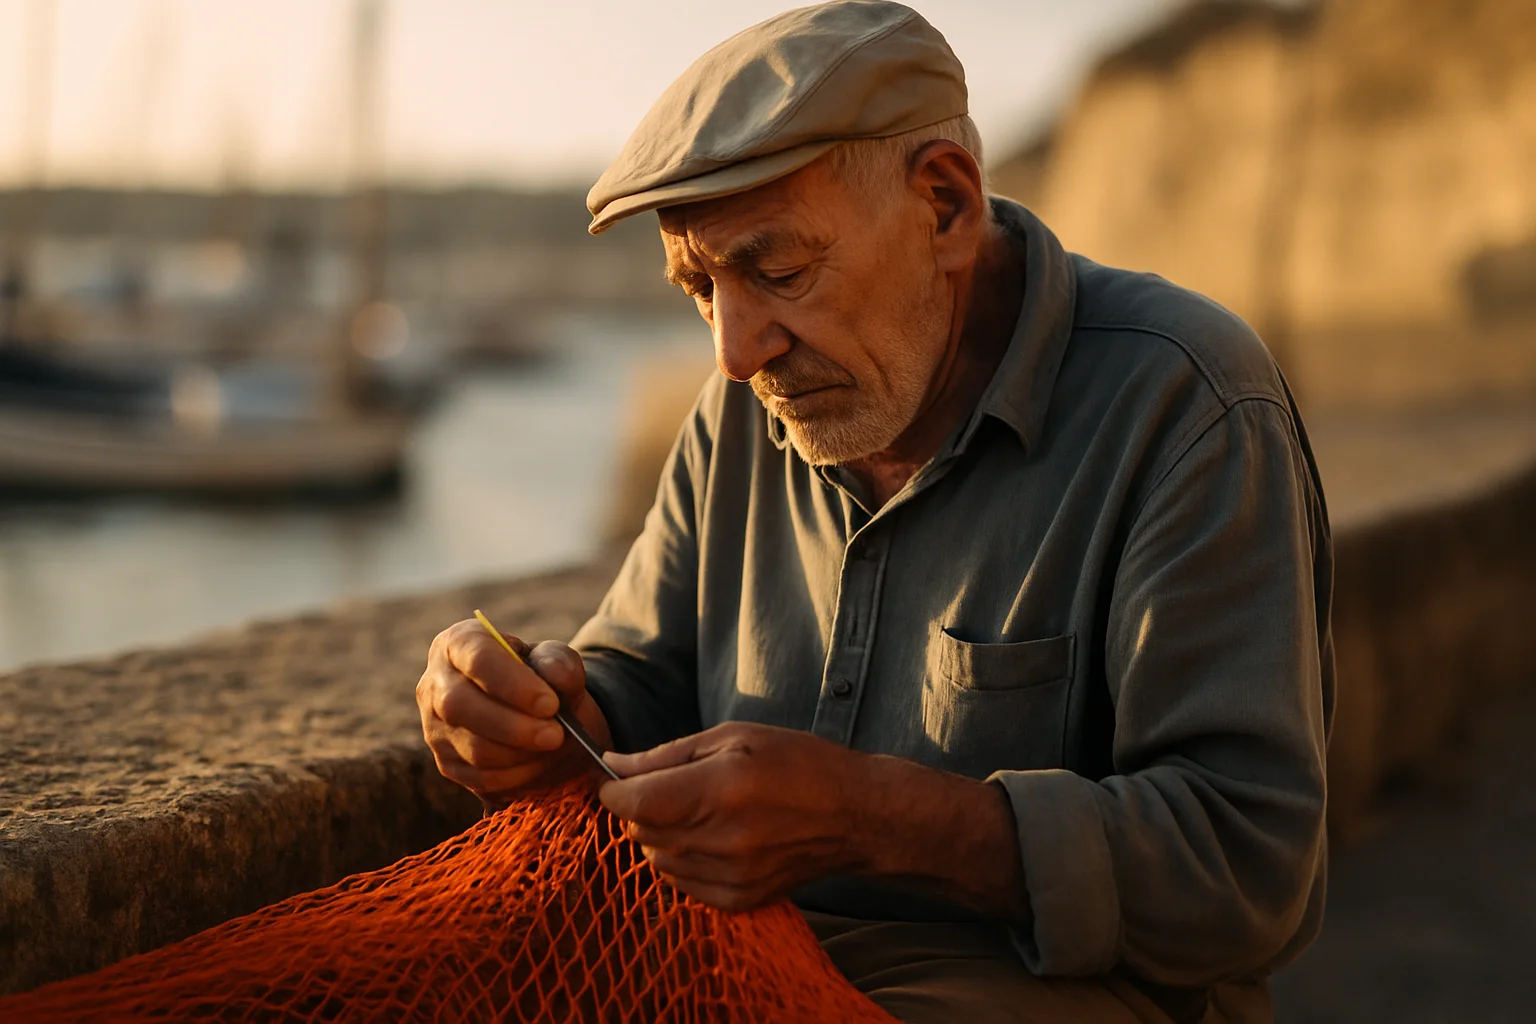
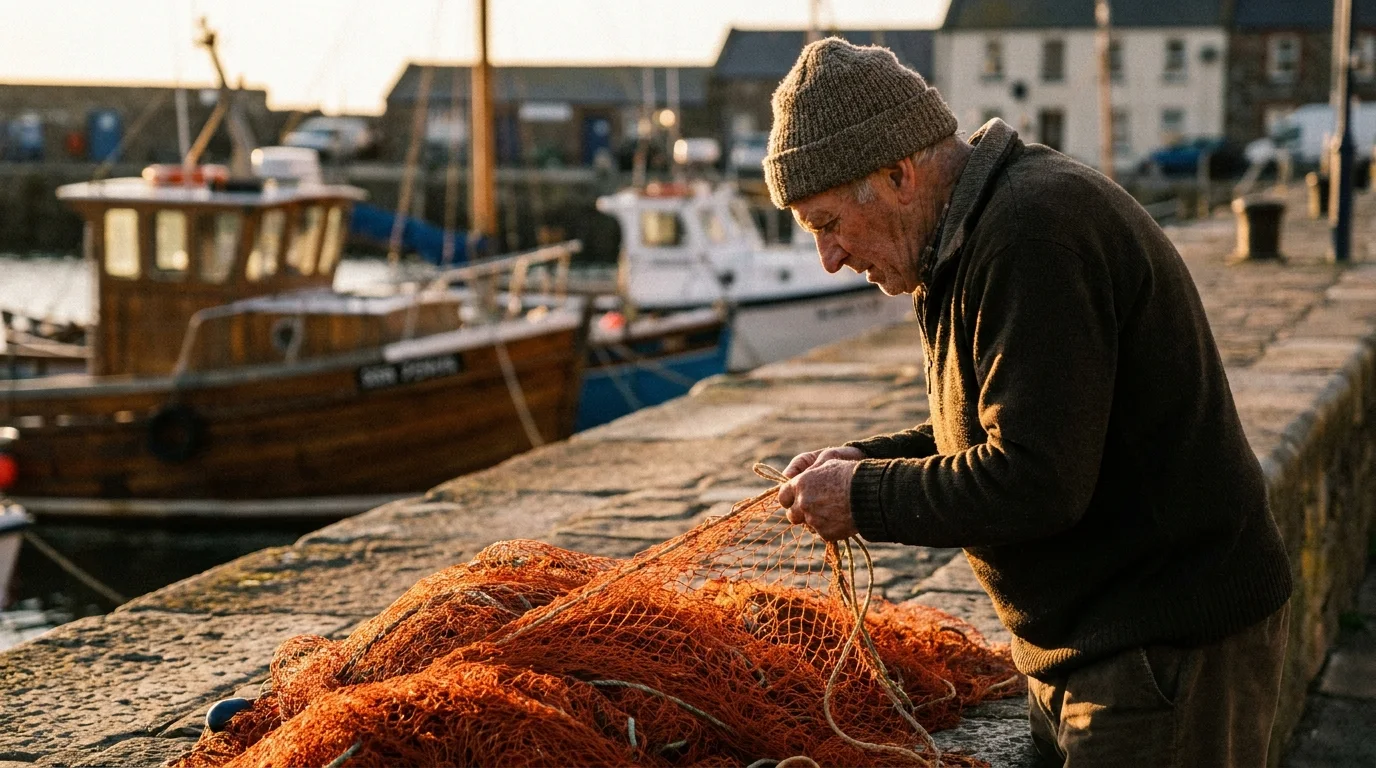
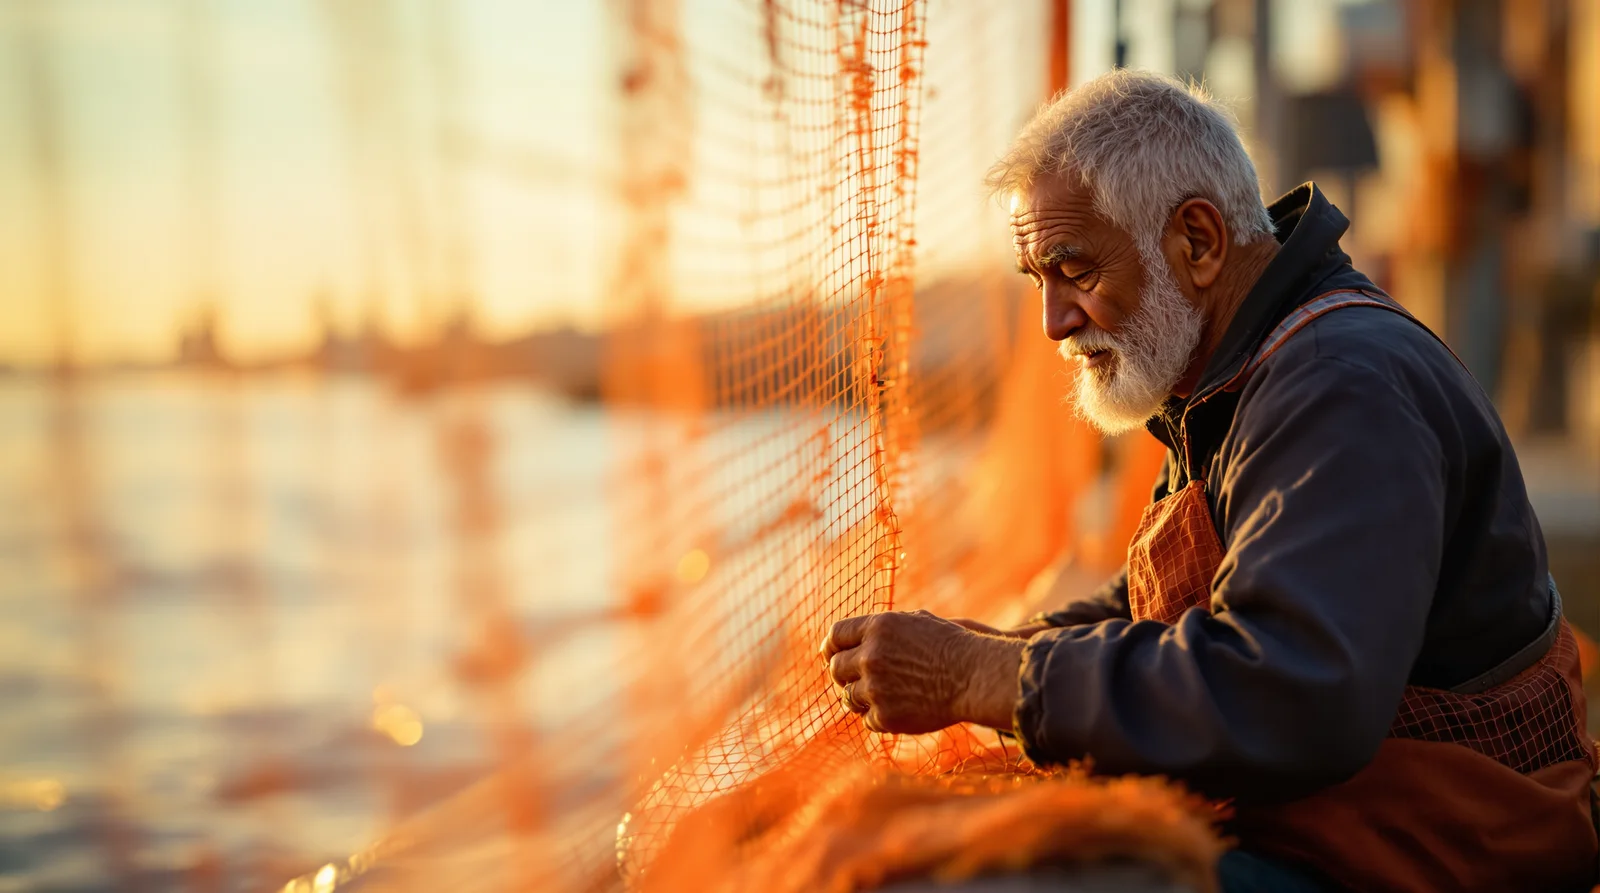
“Candid street photograph of an elderly fisherman mending a bright orange net on a harbour wall at golden hour, 85mm lens, shallow depth of field, natural skin texture.”
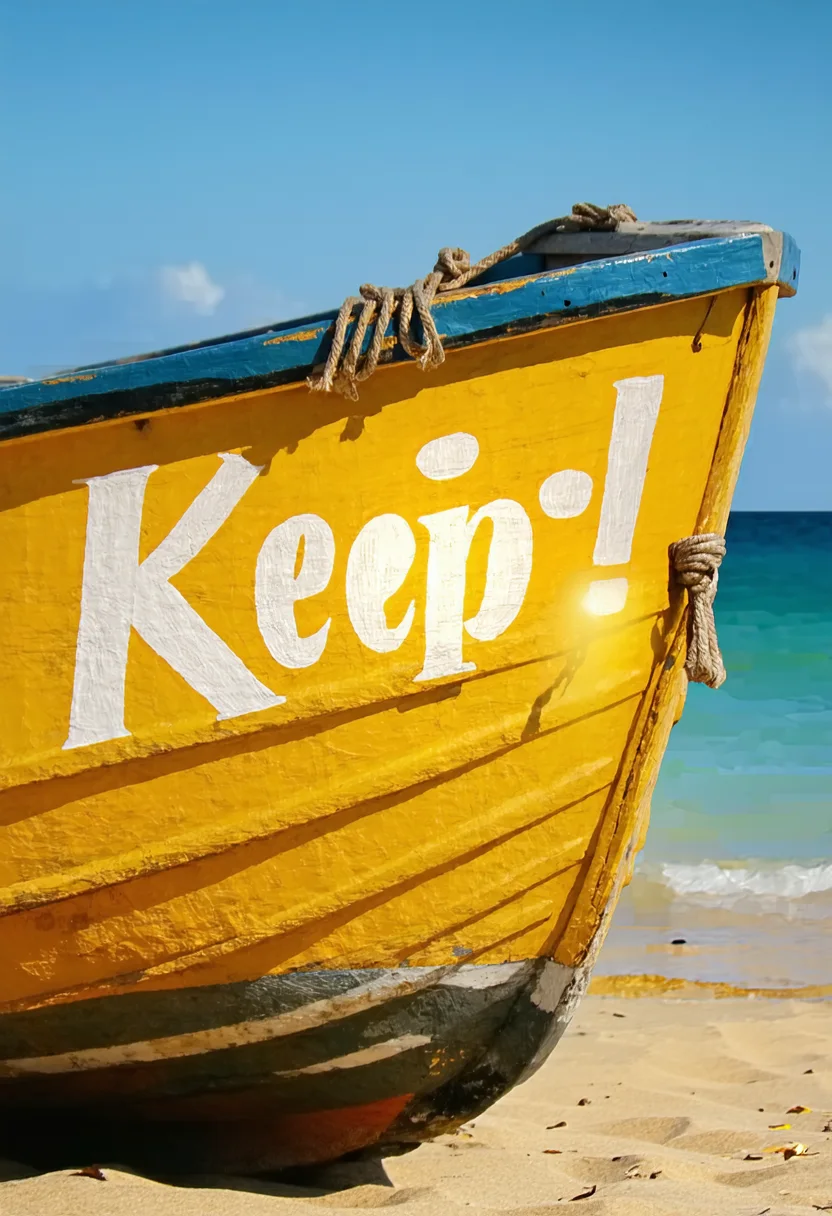
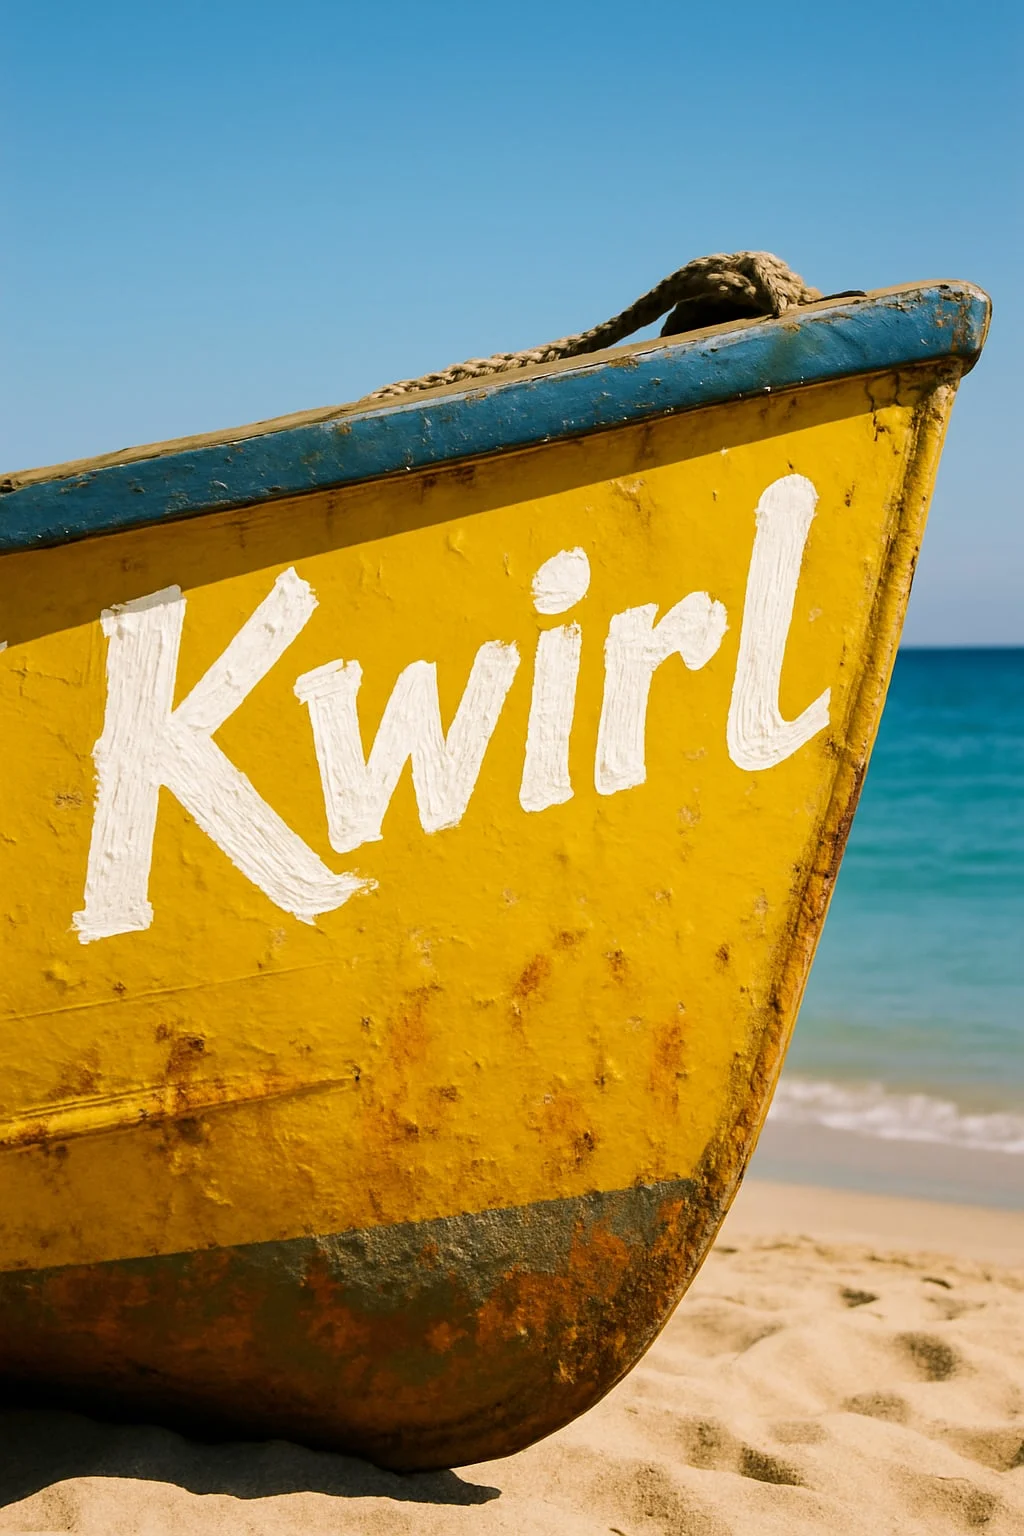
“Turn this into a calm blue-hour scene: warm lanterns glowing on the boat, first stars in the sky, keep the boat and lettering exactly as they are.”
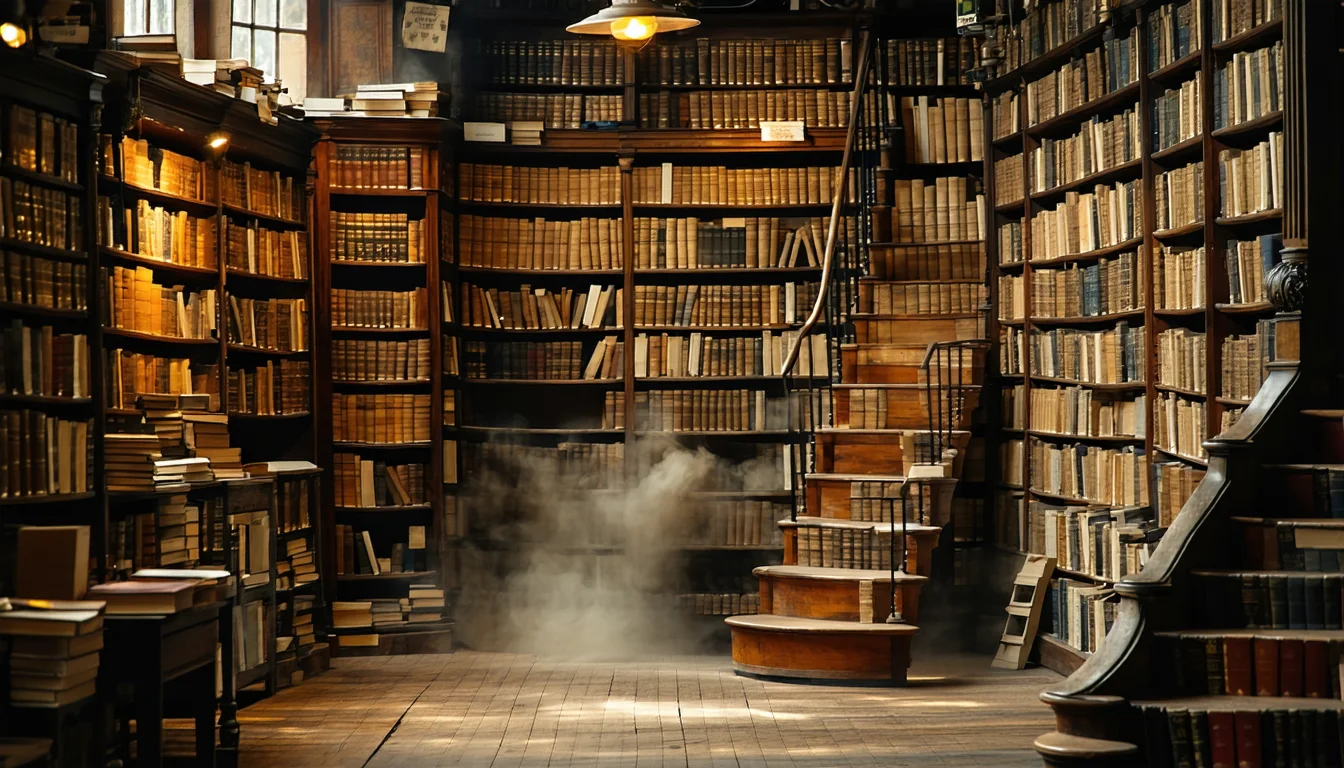
“Photo of an old bookshop interior with towering shelves, a rolling ladder and warm lamplight, dust in the air.”
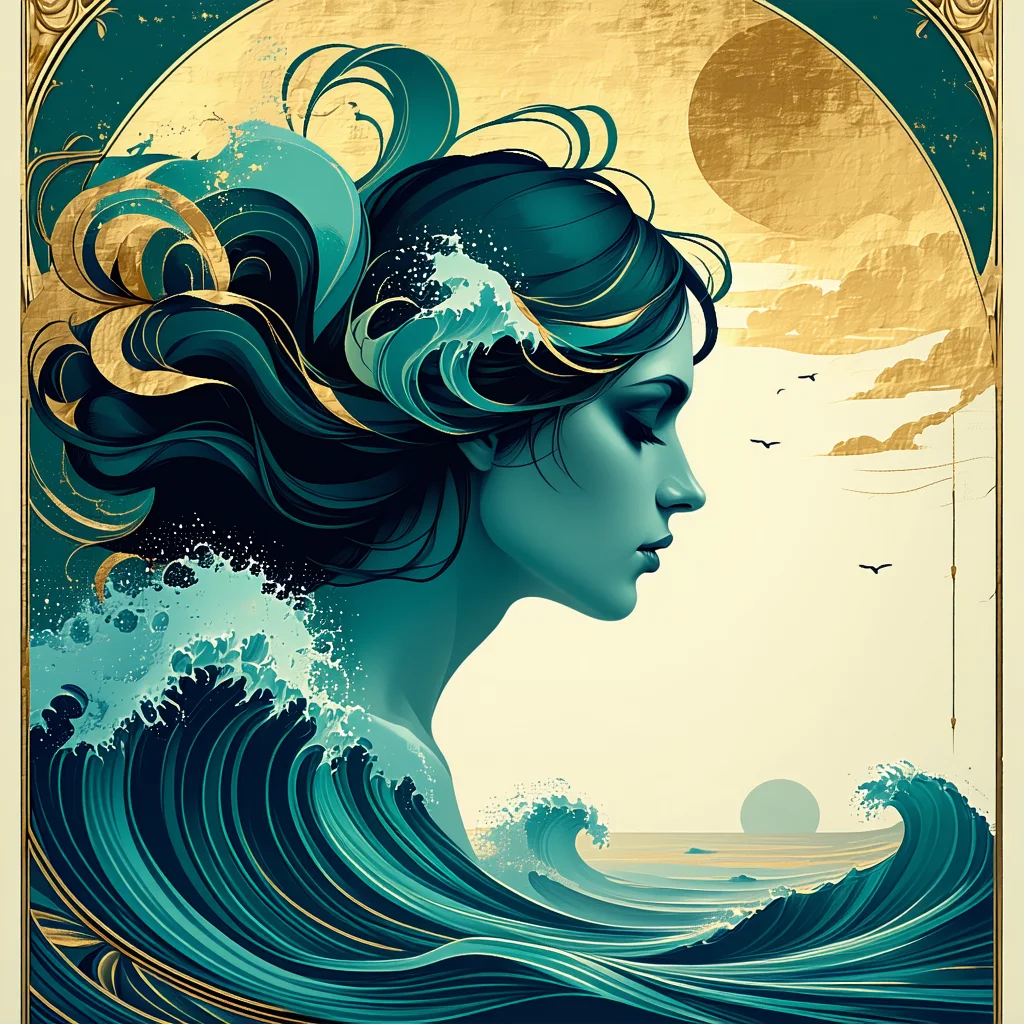
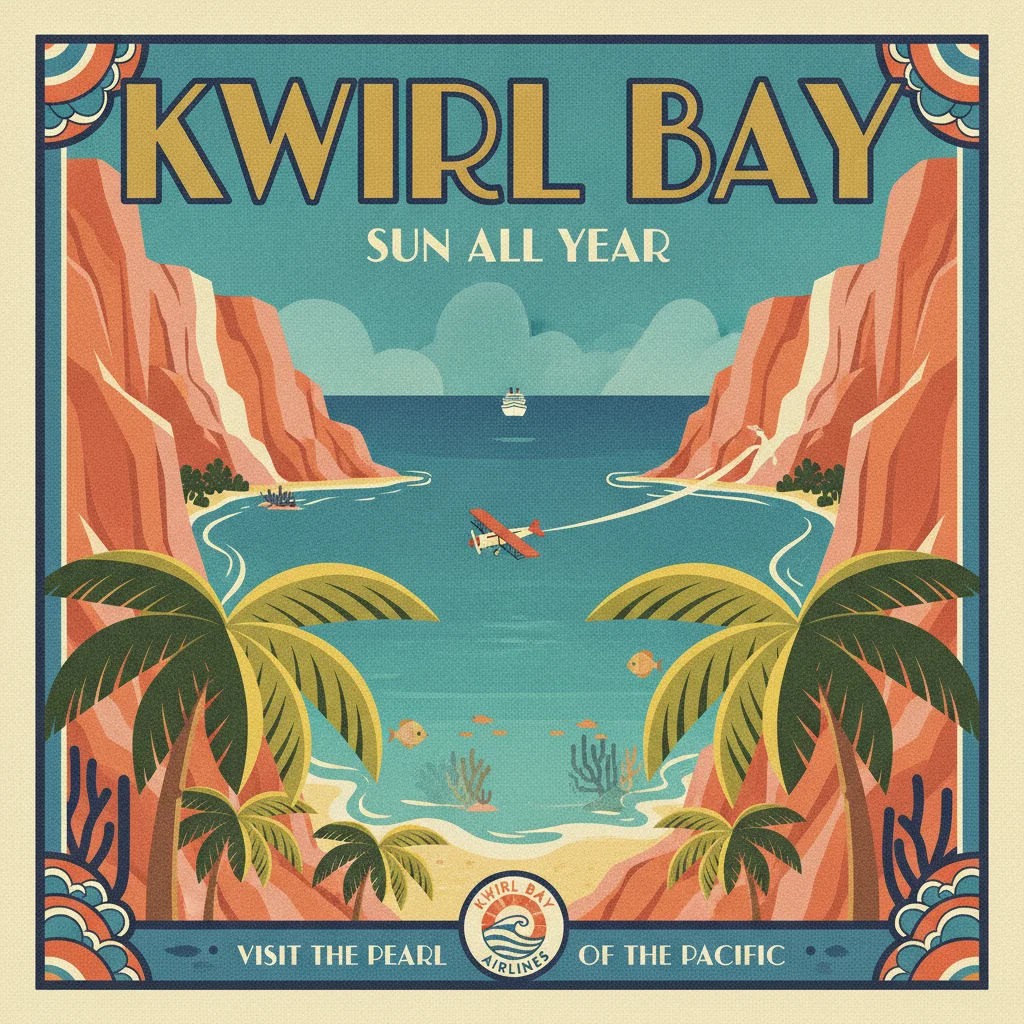
“Art nouveau poster of a woman with flowing hair made of ocean waves, gold and teal palette, ornate border.”
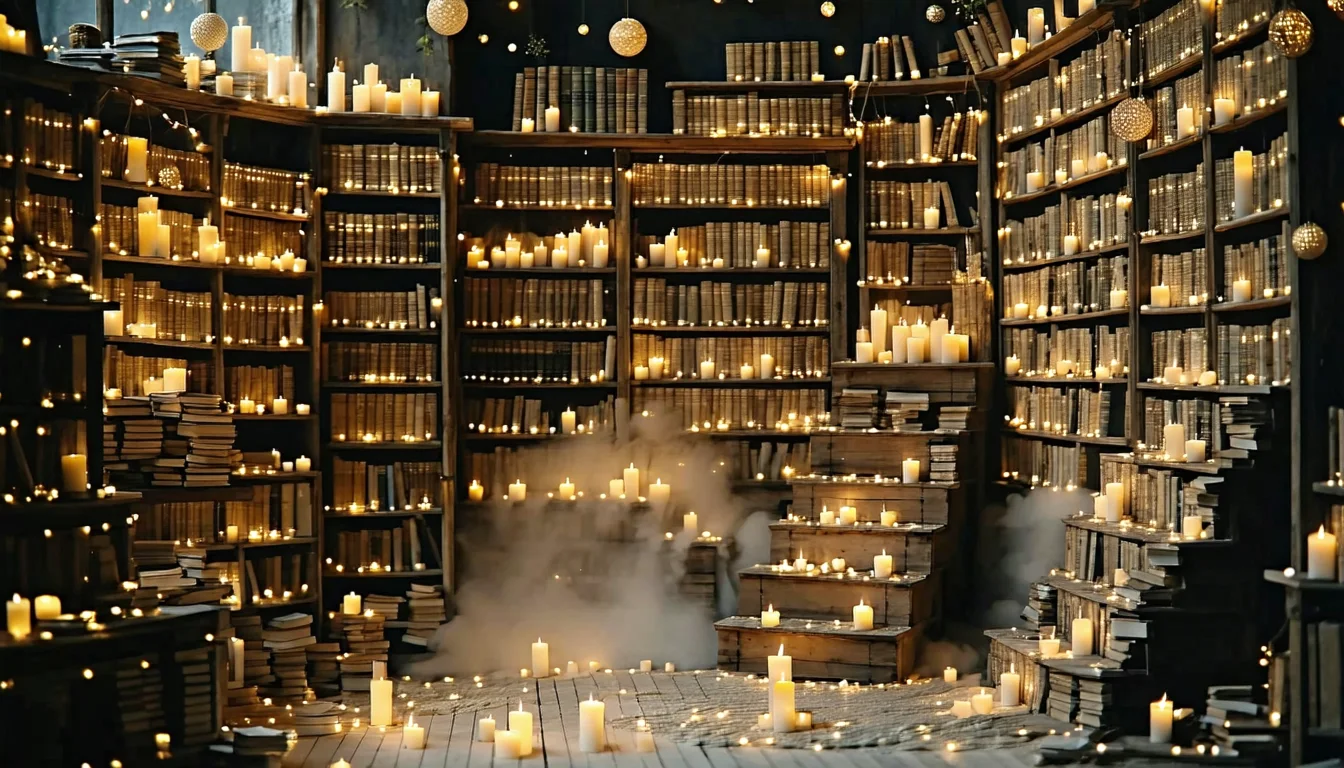
“Turn it into a night scene lit only by candles.”
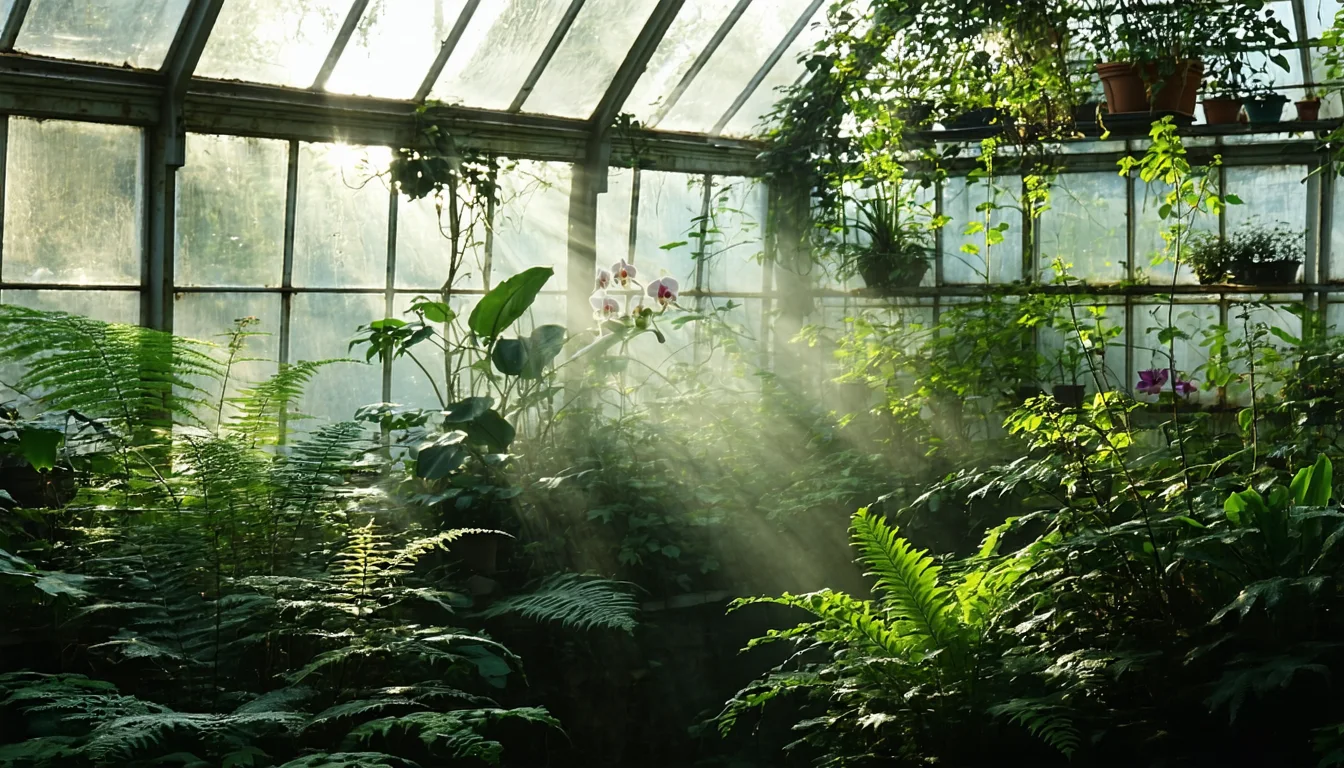
“Photo of a glass greenhouse full of ferns and orchids, morning mist, sunbeams through the panes.”
Specs
Detailed generations with image-to-image support.
- Aspect ratios
- 1:1, 16:9, 9:16, 4:3, 3:4
- Images per request
- Up to 4
- Edits a reference image
- Yes
- Negative prompts
- Yes
Compare with
 OpenAIPopular
GPT Image
OpenAI image model with excellent prompt adherence and editing.
 Google
Nano Banana Pro
Google's most detailed image model, photoreal and great at text.
 Google
Nano Banana
Gemini image model for conversational edits and consistency.
 Black Forest Labs
FLUX1.1 Pro Ultra
Black Forest Labs' high-resolution photographic model.